Dec 5, 2020◆11 min read
Scaling WordPress: from bigger servers to a decoupled frontend
Years of tuning PHP and MySQL, a Kubernetes and Helm cluster that finally scaled WordPress, and why moving the interface out of it was still the change that mattered.
Originally published December 5, 2020. Edited for clarity, expanded with the scaling history that led up to it, and illustrated in September 2026. This account describes the choices I made through 2020, not the current capabilities of these products.
For more than ten years I built and ran client websites largely on my own. The stack that made that possible was integrated: a VPS running cPanel/WHM, WordPress, and themes and plugins that handled much of the heavy lifting. One person could deploy a site, keep it secure and ship changes quickly.
For most of those years, scaling that stack meant making one server bigger. In 2020 I stopped doing that and changed the shape of the stack instead. I kept WordPress, but moved the interface out of it into a separate Vue and Nuxt application that fetched content over an API. By then I had already built a Kubernetes cluster that scaled WordPress properly, PHP and database both. This is the story of why the decoupling, and not the cluster, was the change that mattered.
Why the old stack worked
The server side was a RedHat/CentOS VPS with Apache, MySQL and PHP, administered through WHM. Hosts changed over the years, from Rackspace and ServInt to Contabo, AWS and Heroku. Once its quirks were worked out, WHM needed little day-to-day attention: updates, backups, monitoring and occasional tuning of PHP, Apache, MySQL and DNS. Security took real work. I ran tools such as CSF, LFD and CXS to block hostile addresses and add a layer of protection around applications whose plugins had a steady history of vulnerabilities.
On top of that sat WordPress with commercial or open-source themes. As a one-person operation, leaning on that ecosystem was a rational choice. Other developers had already built and tested the general-purpose parts, and I could spend my time on the user experience and on custom logic written as plugins and theme extensions.
It had costs I felt more each year. Premium themes carried a lot of code written for every possible site, most of which a given page didn't use. Caching, minification and deferred loading helped, but the overhead was built in. Debugging could mean digging through several security layers, and JavaScript conflicts between plugins from different authors were slow to resolve. As mobile traffic grew, those costs showed up most on phones.
What "scaling PHP" meant in practice
WordPress rebuilds every page from the database on each request unless something in front of it says otherwise. Under load, the failure order was consistent, and I learned it on nights when a client ran a campaign or a post got picked up somewhere.
First the PHP process pool filled up. Apache with mod_php, and later PHP-FPM, had a fixed number of workers. Each request held one for the entire time the database took to answer. When the pool was full, new requests queued, then timed out. Raising the worker count helped until memory ran out, because every worker carried the full footprint of WordPress plus whatever plugins the theme had pulled in.
Then MySQL became the bottleneck. WordPress's schema is flexible and its queries are generous. Options load on every request. Plugins store serialized arrays in wp_options and wp_postmeta and query them with LIKE. A few popular plugins ran queries that were fine at ten thousand rows and not fine at a million. Slow queries stacked, connections piled up and the process pool filled again, this time waiting on the database.
The fixes were the usual ones and they worked, in order of how much they mattered: a full-page cache so most visitors never reached PHP; an object cache in Redis or Memcached so repeated queries stopped hitting MySQL; OPcache so PHP stopped recompiling files; tuned InnoDB buffer sizes; a CDN for media. After that, hardware. A bigger VPS bought time, and time was usually what a campaign needed.
Swipe diagram to explore →
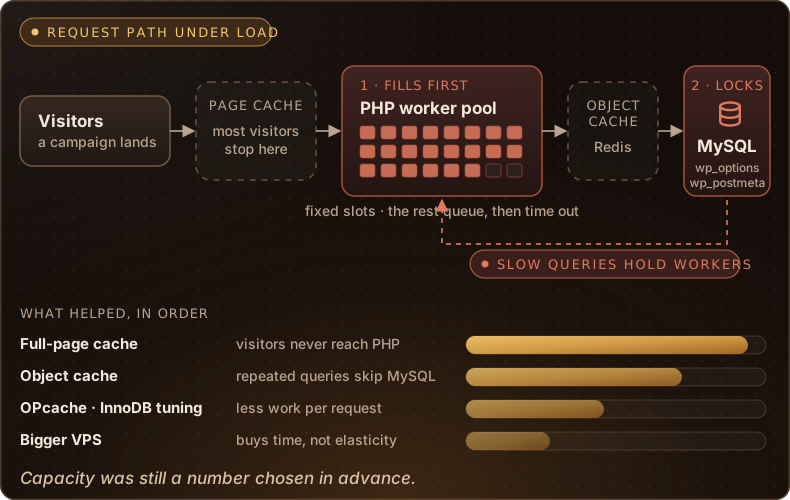
What none of it did was make a site elastic. Capacity was a number I chose in advance. Too low and the site fell over on the day it mattered. Too high and the client paid for idle servers eleven months of the year.
The Kubernetes cluster
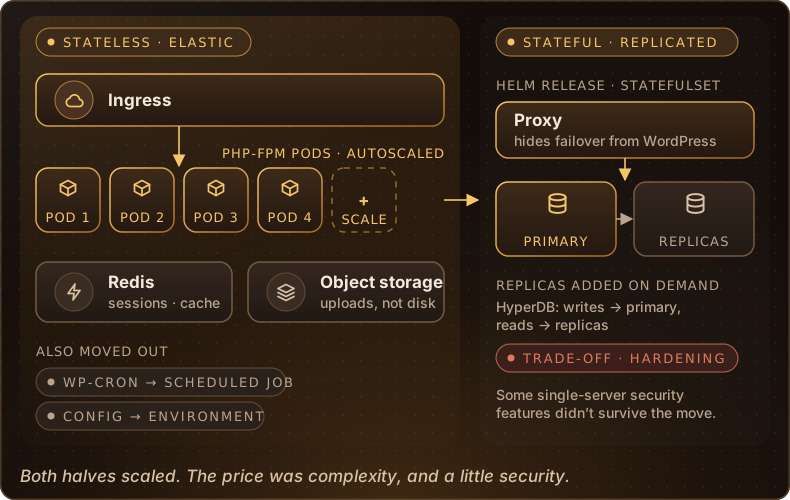
Containers changed what a deployment was. Instead of a server I nursed for years, I had an image I could build, test and throw away. Kubernetes turned that into a system: run this many copies, replace the ones that fail, add more when CPU goes up, put them behind one address. Helm made the whole arrangement reproducible: WordPress, Redis, the ingress, the storage and the database described as one release, with values I could override per client.
For the PHP side of WordPress that fit well, once I had done the work of making it stateless. Uploads moved out of the container to object storage; sessions and transients moved to Redis; wp-cron became a real scheduled job; configuration came from the environment instead of a wp-config.php edited by hand on one machine. The PHP pods became interchangeable and an autoscaler could add them when a campaign hit. The first time that happened without me, after years of doing it by hand at midnight, was a good night.
The database was the harder half, and it took longer, but it worked too. MySQL doesn't become horizontal just because it runs in a StatefulSet, and WordPress out of the box assumes a single database. So the Helm release grew a primary, read replicas I could add on demand, and a proxy in front to hide failover from the application. Inside WordPress, a drop-in database class such as HyperDB routed writes to the primary and reads to the replicas. I had to decide what happened when a plugin wrote and read in the same request; most tolerated the replica lag once the routing rules were right, and the few that didn't got pinned to the primary. Persistent volumes with the right storage class, a chart that handled primary election, backups I had actually restored: all real work, all done once and then reused.
The result was a WordPress that scaled in both directions, PHP and data, without me at the keyboard. What it cost was two things. The first was complexity: a server I understood completely became a system I had to keep understanding as it changed. The second was security. A few of the protections that came for free on a single hardened server didn't survive the move to pods, shared volumes and a database reachable from many places, and I chose to accept that rather than rebuild every one of them. For the sites that needed the scale, it was a fair trade.
Swipe diagram to explore →
For a client with one site and a modest budget, though, it was more infrastructure than the problem deserved. And running it taught me something the cluster itself couldn't fix.
Where the boundary actually was
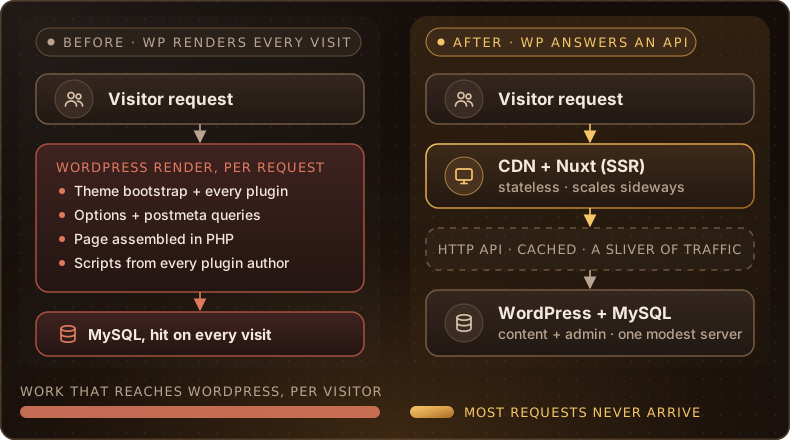
The cluster worked by absorbing load. It didn't reduce it. The load I was fighting came from WordPress rendering pages: PHP running the theme, the theme running every plugin, every plugin touching the database, on every request. Caching hid that path. Kubernetes multiplied it across more pods and more replicas. Neither changed where the interface lived, so every visitor still paid for a full render somewhere.
In the integrated setup, the theme, the content application and the database were deployed as one unit. Every interface change happened inside WordPress's rendering model and alongside every plugin's scripts. Every visitor paid for that model, and every scaling exercise was an exercise in making that model survive.
Swipe diagram to explore →
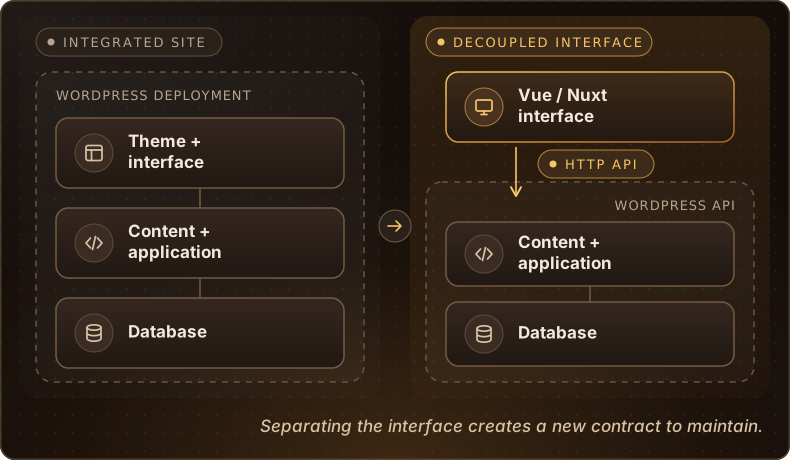
I wanted to build the interface as its own application: choose its framework, control exactly what JavaScript shipped to each page, and combine data from more than one source. That meant moving the interface outside WordPress and talking to it over HTTP.
WordPress still did what it was good at. It remained a PHP application with a MySQL database and an admin that clients already knew. It simply stopped rendering the public pages. And once it stopped rendering pages, the traffic that reached it was a small fraction of what it had been: API calls for content, cached aggressively, instead of a full theme render per visitor. The PHP pool and the replicated database that had needed a cluster now needed one modest server, and the security I had traded away for scale came back with it.
What I separated
The experiment that proved the approach was an app hosted on EC2. The Nuxt frontend ran on Node.js behind an Nginx reverse proxy with SSL and HTTP/2, and pulled from four separate sources:
- a portfolio API from a WordPress instance on my cPanel VPS;
- a news API from another WordPress instance on the same VPS;
- a currency exchange API, which I wrote as a Dockerized Python app on EC2;
- media from simple file hosting on the VPS, used as the app's CDN.
Swipe diagram to explore →
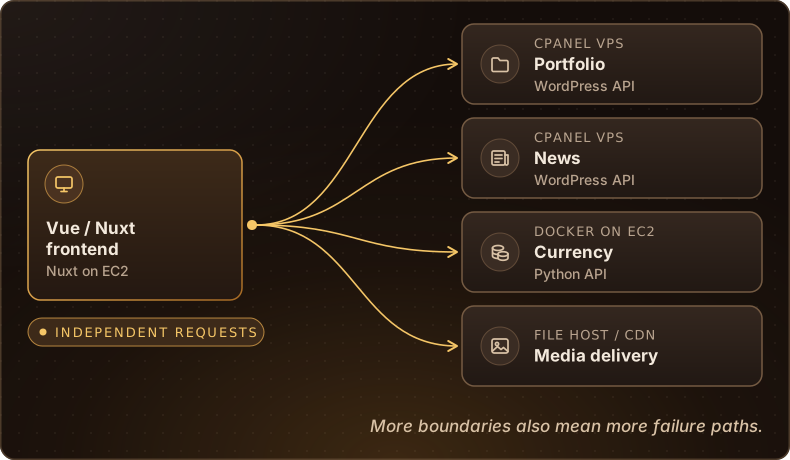
The original title called this a move to microservices. That overstated it. What I had was a decoupled frontend with a few supporting services, each deployed separately. Nothing in the setup involved service orchestration, queues or independently scaled services. It was a useful step, and a smaller one than the word suggests.
Nuxt made the frontend practical. Its universal mode rendered each page on the server, so the first response contained real HTML rather than an empty shell, which helped first loads and crawlers that handle scripts poorly. It also split code per page, prefetched linked pages, and offered a PWA module for caching and offline behavior. The frontend was stateless in a way WordPress had never been, which meant the scaling story I had wanted from Kubernetes came almost for free: more Node processes behind the proxy, and a CDN in front of pages that rarely changed.
What improved, and what became my problem
I got the control I was after. I could ship only the code each page needed, deploy frontend changes without touching the WordPress installs, and combine several data sources in one view. The load profile changed from "every visitor renders WordPress" to "WordPress answers a cached API," and the servers behind it got smaller, not bigger.
Swipe diagram to explore →
The boundaries came with work attached. Each API was now a contract: if a WordPress plugin changed the shape of its JSON, the frontend broke even though both sides were individually fine. Every request crossed a network, so each source needed its own handling for slow or failed responses. There were more deployments to coordinate, more servers to patch and more places to look when something went wrong. And development took longer than it would have on a premium theme.
The original article ended with specific load times and called the result "a dream come true." I've removed those numbers because I don't have the test setup behind them. The honest summary is that the interface became faster to change and easier to shape, the system as a whole became more complicated to run, and the scaling problem I had spent years on became a different, smaller problem.
Where I would still use the simpler stack
For many of the sites I built, the integrated WordPress stack was the better answer: a small business site, a content-heavy site edited by non-developers, anything where a mature theme covered most of the need and one server with good caching was easier to maintain than four services. Decoupling pays off when the interface needs a life of its own, has to combine several data sources, or carries traffic that a theme render can't survive. Otherwise it mostly adds boundaries to maintain.
Every boundary I added gave me a new choice and a new failure path. The useful question was never which architecture is more modern, and it wasn't how many pods I could run. It was where the work actually happened on each request, and whether a particular project needed to move that boundary enough to pay for it.